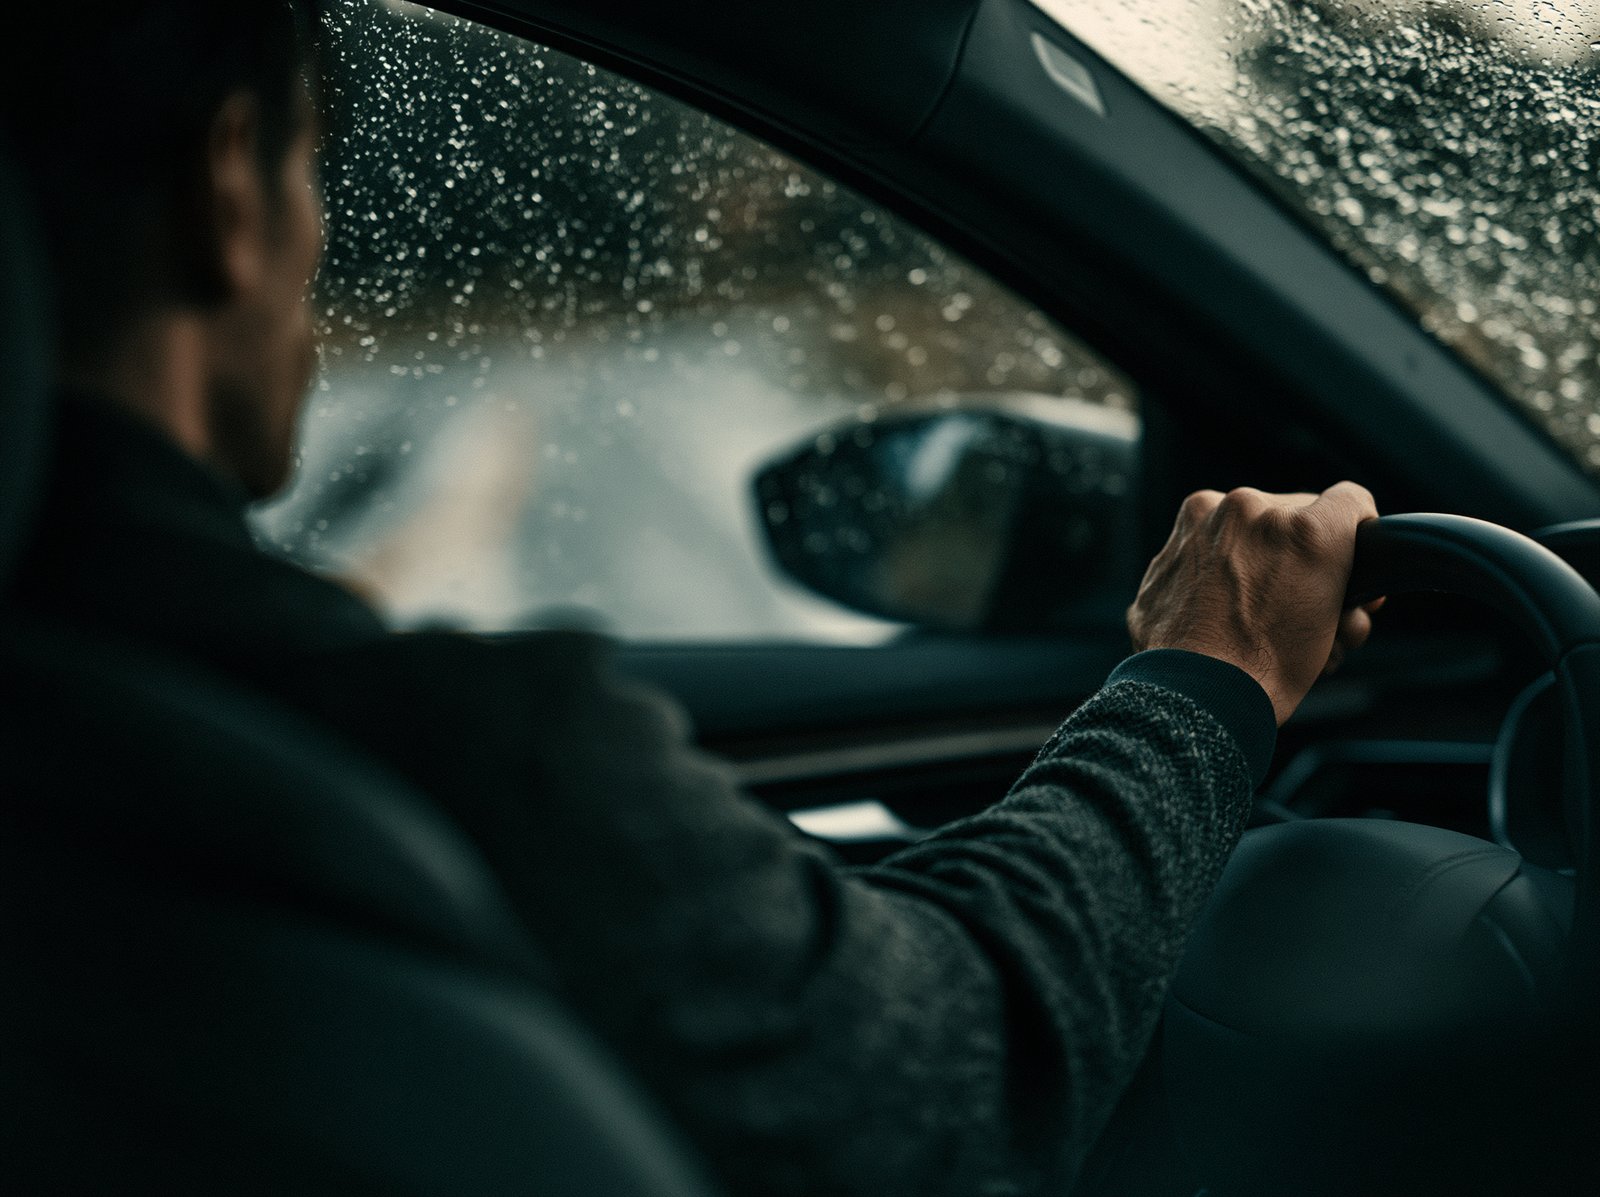
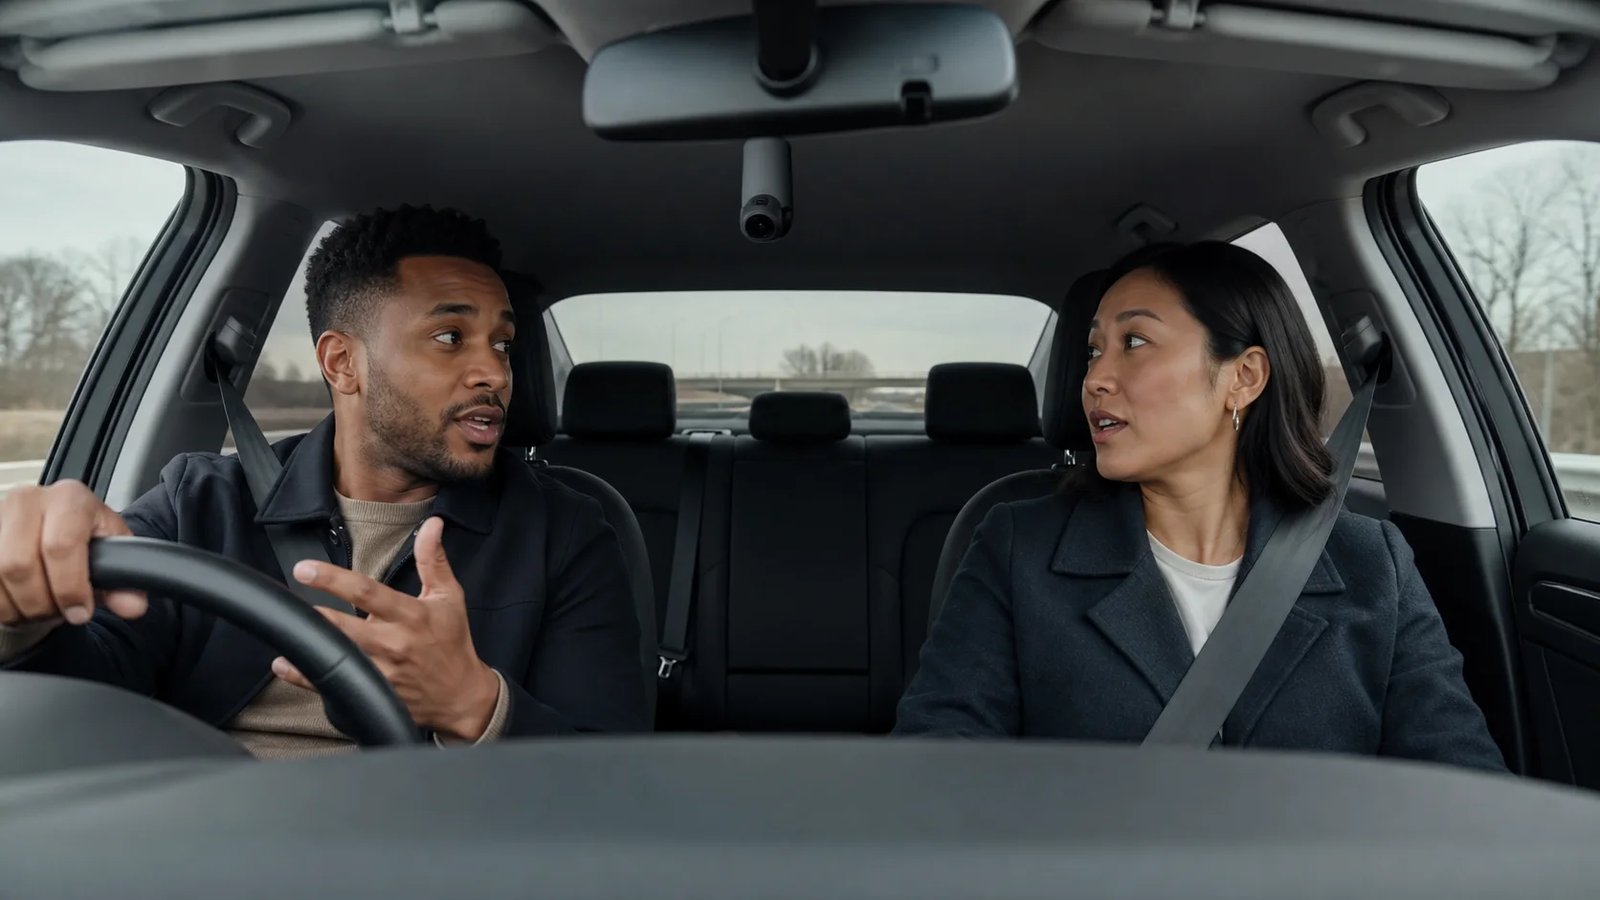
Speech data for automotive voice recognition, recorded in the cabin, then annotated and evaluated.
YPAI records native speakers in real cabin conditions. Dialect and accent coverage. HVAC, road and passenger overlap. Consent evidence and a QA package with the delivery.
Norwegian legal entity · EEA residency by default · DPA per engagement
Session · motorway · cabin micsch 2/4 · 48 kHz
dialect · wake
dialect 00:02.1-00:08.4 HVAC 00:05.0-00:06.8 wake word 00:08.42 command 00:08.9-
150 +
Languages available through the YPAI contributor and specialist network
210,000 +
Contributors in the network. Availability per market is set at scoping.
Native
Speaker recruitment and recording in the required language markets
Real cabin
Engine, HVAC, road surface, open windows, passenger overlap, music and device variation
Selected automotive voice programmes
Collection, annotation and evaluation work across OEM and Tier-1 voice programmes. Relationship and scope vary by engagement.
The model does not hear a standard speaker. It hears the driver.
YPAI scopes the locales, dialects, speaker profiles and cabin acoustics that decide whether in-car speech still works on the road.
Highway noise, HVAC, open windows and overlapping passengers shape the signal. Dialects, accents and age or speaking-style variation change recognition. Consent, metadata and QA records determine whether the speech package can ship.
Specify the speech package the cabin actually needs.
The brief can cover one acoustic or language gap, or the full chain from speaker recruitment through accepted annotation.
Speech collection programmes
01
Wake-word, barge-in and hard negatives
Positive examples, confusable negatives, far-field cabin capture and accent variety.
02
Dialect, accent and speaker-profile coverage
Native-speaker recruitment against the target locales, regional varieties and buyer-defined age or speaking-style cohorts.
03
In-vehicle acoustic conditions
Highway and city noise, HVAC, open windows, device position and multi-passenger overlap recorded in real cabins.
Annotation and acceptance programmes
04
Transcription, intent and metadata
Automotive terminology, command and intent labels, speaker and seat metadata, device and acoustic tags.
05
QA package and acceptance criteria
Multi-stage review, error categories and an acceptance record the buyer can use before scale-up.
Locale, dialect, cabin, rights and acceptance requirements turn this scope into a speech-data specification.
One in-cabin speech project, three practical starting points
Three ways to enter the same controlled delivery.
Build a cabin corpus for a new market
For a new locale, dialect set or cabin-microphone profile.
Turn speaker profiles, scripts, devices and acoustic requirements into a capture and annotation plan, then deliver an accepted corpus with the agreed metadata and labels.
Close dialect or acoustic gaps
For a system that fails on regional speech or real driving noise.
Use model outputs and failure cases to isolate gaps by locale, speaker profile or cabin condition, then define the right evaluation, review or targeted collection.
Run accepted speech production
For a defined production brief, ready to execute.
Turn the specification, rights model and acceptance criteria into qualification, calibration, production, QA, review, rework and accepted batches.
Mobilisation follows the specification.
The delivery plan takes shape around the actual speech work.
01
Qualification and calibration
Align speaker profiles, devices, review criteria and capture protocol before production begins.
02
First accepted wave
Prove the specification against submitted recordings, then use the accepted batch to set the working forecast.
03
Rolling delivery
Recruitment, capture, review, rework and replacement coverage move together against the programme brief.
The forecast uses the unit that matters to the programme: accepted speaker-hours, recordings, sessions or assets.
AI DATA & EVALUATION
Speech data you can stand behind.
Managed collection, annotation, validation and evaluation.
A managed data operation, accountable for every accepted batch.
Road noise, HVAC, dialect and spontaneous speech change what must be collected and how recognition is judged.
CollectionCapture speech in motion.Drivers, passengers, road surface and weather.AnnotationMark usable speech.Turns, intent, dialect tags and speaker metadata.ValidationTest the acoustic range.Noise, cabin character and language variation.EvaluationJudge recognition in context.Does the command still hold while driving?
One record runs the whole project.
For work YPAI manages, our collection platform connects:
One shared recordYPAI-managed work
Reviewers and operations teams see the same task status and version history.
Qualification
eligibility
qualification
quotas
Planning
scheduling
invitations
consent and rights
protocol versions
Collection
collection
uploads
Verification
checksums
technical QC
Native review
native human review
specialist review
Re-recording · rework · replacement · rejection
Failed recordings return for re-recording, rework, replacement or rejection according to the project rules.
Acceptance
dataset assembly
Delivery
versioned batches
manifests
secure delivery
Accepted material moves into versioned batches, manifests and secure delivery.
Role-based dashboard and client-portal access can be provided for YPAI-managed work.
Progress and quota viewssupport
Coverage decisions
QA, issue and rework viewssupport
Remediation decisions
Accepted-volume and manifest viewssupport
Delivery readiness
Operating model
The operating model can use YPAI-managed infrastructure, customer systems or a hybrid.
API access and custom integrations are available on a project-specific basis.
You can keep your own tools; native-speaker review stays with YPAI.
Start with a pilot
Scope an in-cabin speech pilot.
Studio recordings fail in real cabins. Our automotive voice data covers the dialects, age groups and noise conditions your deployment meets.
We reply inside one EU business day with a feasibility read for automotive programs. Sensor-fusion and validation specs ship with the first reply.
Your confirmation email may be delayed. If you do not hear from us within one business day, write to contact@ypai.ai and quote the reference above.
GDPR-aligned scoping • EEA residency by default • One-business-day response
FAQ
Frequently asked questions
What does YPAI deliver for automotive voice recognition?
YPAI delivers in-cabin speech datasets and annotation pipelines for command-and-control, conversational HMI, and driver-monitoring applications. The deliverable includes consented in-cabin recordings across driver and passenger seats, multi-device captures (OEM mic array, headset, smartphone), command-grammar markup, and intent labelling against the customer-supplied dialogue model. BYD and Cerence AI are YPAI clients in automotive.
How does YPAI collect in-cabin automotive speech?
Collections are run in real cabins with real road noise, infotainment cross-talk and HVAC profile. Speakers are recruited natively per locale, and recordings cover driver-only, driver-plus-passenger and multi-occupant scenarios. Device variety mirrors the deployment hardware so the corpus reflects the acoustic conditions the deployed ASR or NLU model will encounter.
What governance evidence accompanies automotive voice data?
YPAI delivers provenance bundles, traceability of changes, reviewer-qualification records, and dataset documentation structured for the customer audit trail. GDPR controls, EEA processing terms, Article 10 evidence, and project-specific acceptance criteria are written into the DPA and SOW.
Which languages does YPAI cover for in-cabin voice?
YPAI covers tier-1 European and Nordic languages (English-US/UK, German, French, Italian, Spanish, Dutch, Polish, Norwegian, Swedish, Danish, Finnish), major Asian languages (Mandarin, Cantonese, Japanese, Korean), and a growing set of Middle Eastern and Latin American locales. Code-switched speech (common in EU drivers) is annotated rather than collapsed to a single dominant language.
Can YPAI deliver wake-word and barge-in datasets?
Yes. Custom wake-word datasets (positive examples, hard-negative confusables, accent variety, far-field acoustics) and barge-in test corpora (speaker interrupting active prompt playback) are delivered as scoped engagements. The dataset is paired with an evaluation harness so the customer can measure false-accept and false-reject rates against a documented baseline.
Is in-cabin speech collection GDPR-compliant?
Yes, for the collections YPAI runs. Voice data is biometric and special-category under GDPR Article 9, so collections run on explicit consent with identity-of-controller disclosure and an Article 35 DPIA. Recordings stay inside EU residency unless the engagement explicitly authorises a non-EU region. The data-handling stance is documented in the DPA shipped with the SOW.
What makes automotive speech data work different?
The pipeline is built around the customer deployment environment and the EU AI Act data-governance evidence required for safety-relevant in-cabin systems. Device variety, acoustic profile and multi-occupant scenarios are documented against the deployment environment. See in-cabin voice, wake-word and driver-monitoring audio for the full in-cabin scope, and automotive AI data for perception and evaluation work.
Contribute
Do this work with us
We recruit contributors for this kind of work continuously. Openings are listed per
country, with the rate stated in the country's own currency.
Analytics and Google Ads cookies are set only if you accept. They show us which campaigns bring visitors here. Change your choice any time under Cookie settings. Analytics and ad cookies are set only if you accept.Cookie policy